The Challenge
While the underlying research demonstrated the efficacy of the NLP models, raw terminal outputs are inaccessible to end-users. The objective was to package the heavy PyTorch/Hugging Face inference engines into a responsive, real-time tool that writers could use to evaluate their rhetorical strategies dynamically.
System Architecture
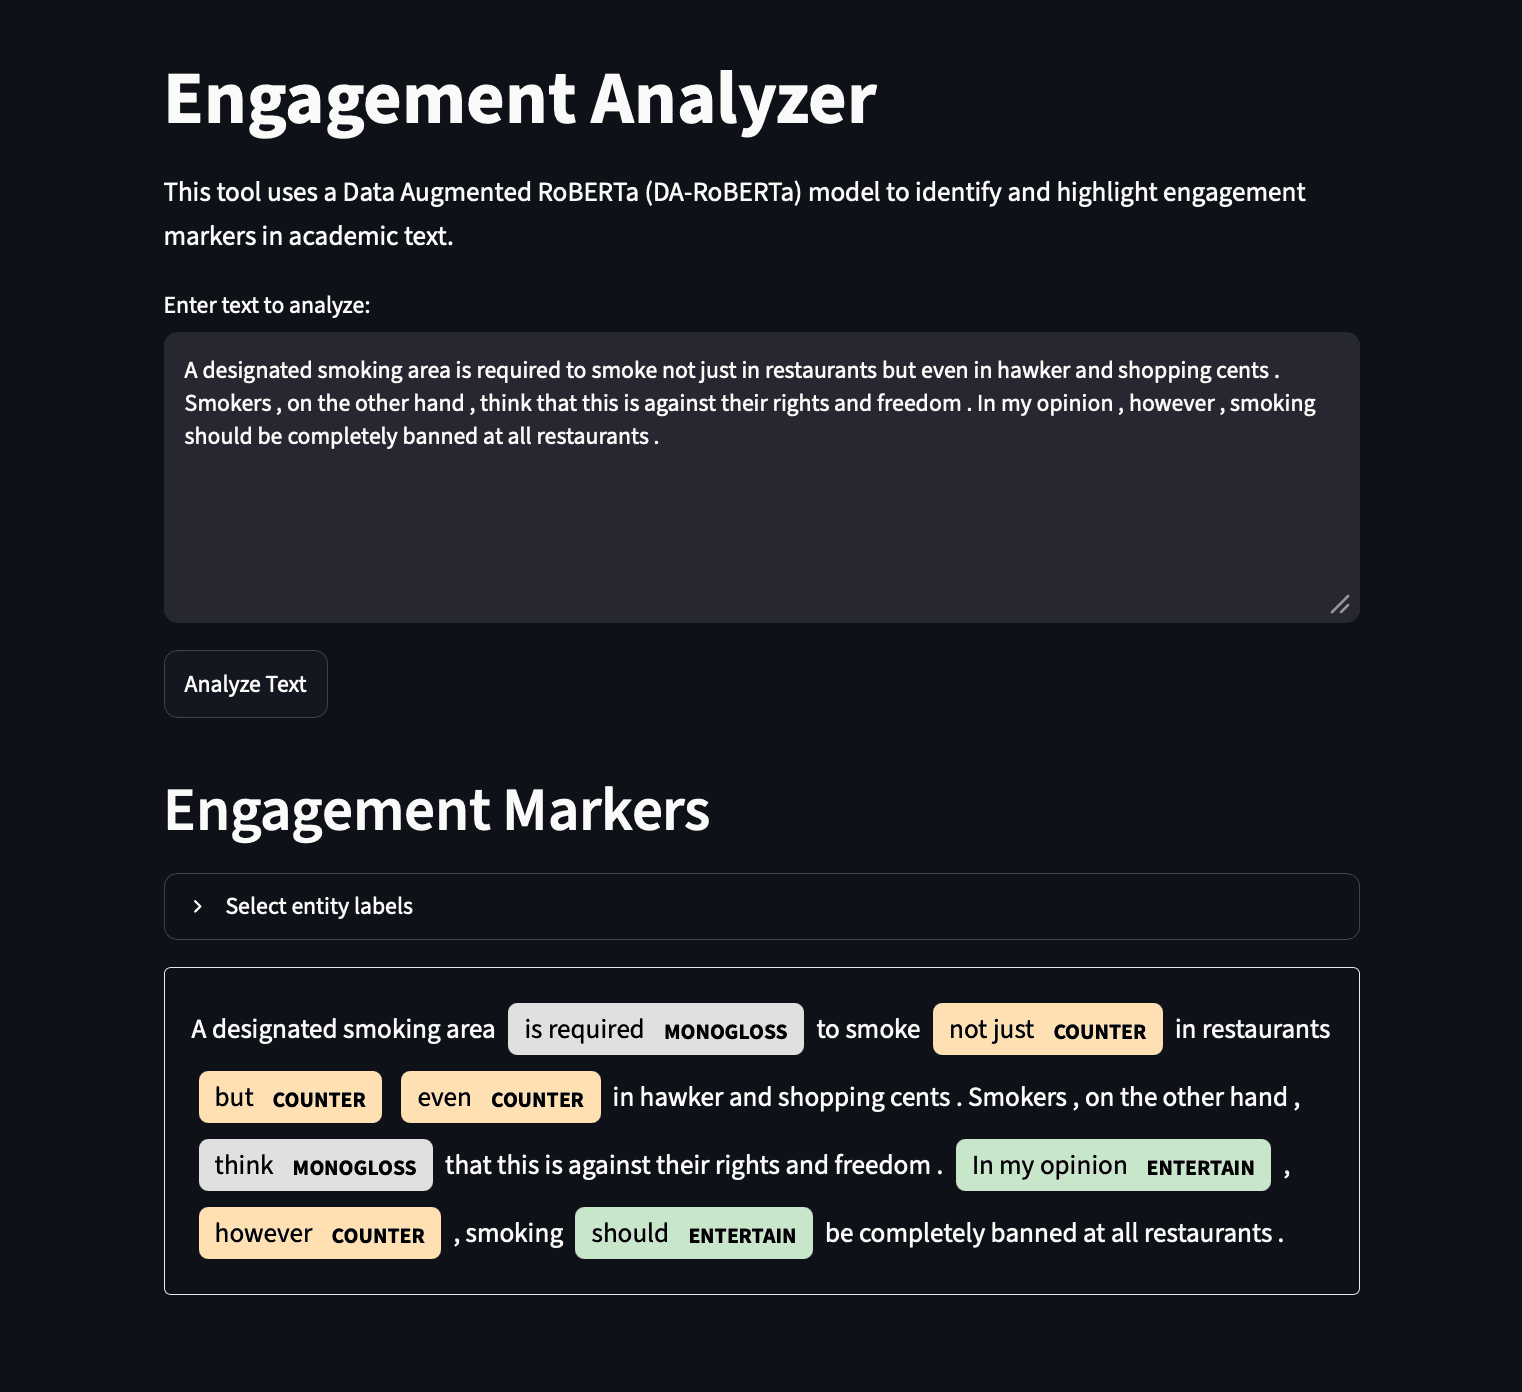
The application wraps the pre-trained NLP models in a Python backend, serving predictions to a Streamlit frontend that instantly highlights discourse and engagement markers in user-submitted text.
Raw Text Input → Streamlit UI → Inference Engine (Hugging Face) → Rhetorical Output & Highlighting
Engineering Learnings
- Model Deployment: Optimized heavy NLP models to run inference fast enough for a smooth user experience in a web environment.
- Frontend Integration: Mapped complex array outputs from the model into human-readable visual highlights on the frontend.
- Latency Reduction: Managed caching and state effectively to prevent unnecessary model reloading on every user interaction.
Web Demo Interface